WBHOT
Long-horizon collection and visual analysis of Weibo hot-search topics and their hosts
- Year
- 2026
- Status
- Active
- Categories
- python / web / tool
- Updated
- 2026.09.30
- Python
- Flask
- ECharts
- Weibo API
- Time Series
Overview
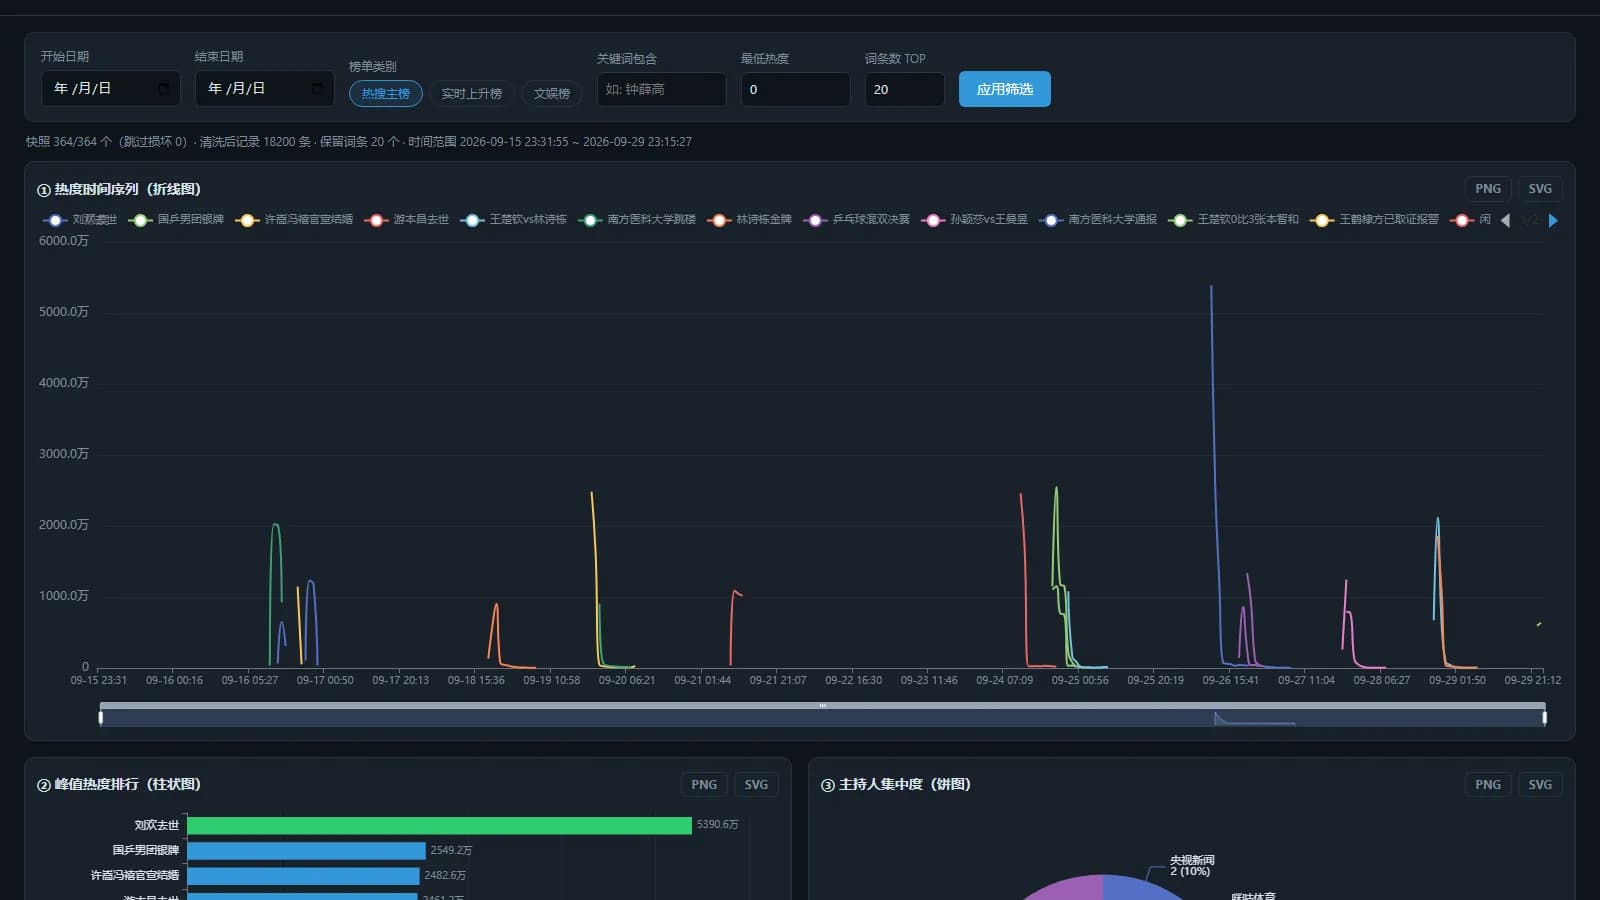
WBHOT is a long-running data collection and analysis system for Weibo hot-search. It calls Weibo's official mobile API on a fixed interval to capture the hot-search boards, topic metadata and post details, persisting each round as a time-series snapshot that cannot be back-filled, and serves a remote admin panel plus a publication-grade visualisation page.
The project supplies empirical data for a study of agenda-setting in hybrid media ecosystems: who actually initiates and drives a trending topic, and how much agenda weight each layer holds — platform mechanism, verified media, and individual cognition.
Problem
Weibo's hot-search only shows what is on the board at this moment; historical boards cannot be retrieved. Questions about agenda leadership depend precisely on long-horizon data, so every day the collection starts late shortens the usable time series.
Three constraints at the API level:
- The board endpoint returns only rank and heat value, with no information about topic ownership;
- Host, media publication count, read count and discussion count live behind the topic-detail endpoint, requiring one extra request per topic;
- Anonymous requests are rejected outright — the board returns 432 and topics return
ok:-100. A guest-cookie flow and TLS fingerprint emulation both failed; a logged-in session is mandatory.
Together these turn the task into a data-engineering problem that has to start early and then run unattended, rather than a one-off scraping script.
Architecture
Weibo Mobile API
↓
spider.py  (hot-search boards + topic detail + host parsing)
↓
JSON snapshots  (one file per round, ~23KB)
↓
web.py     (Flask admin panel + aggregation API)
↓
ECharts visualisation / pivot table / CSV export
Features
- Zero cost: calls the official mobile API directly, replacing a usage-billed third-party scraping service
- Host parsing: extracts host, media publication count, read count and discussion count from the topic header card, as a directly observable indicator of agenda leadership
- Long-horizon snapshots: one JSON file per round on a fixed interval, designed for unattended long-term operation
- Remote admin panel: start and stop the task, adjust parameters, refresh the session online, tail logs, package and export data
- Expiry alerting: pushes an iOS notification when the session expires, so collection never stalls silently
- Publication-grade visualisation: line / bar / pie / scatter / heatmap charts plus a pivot table, with linked filtering and PNG / SVG / CSV export
Data
Collection status as of 2026-09-29:
Continuous run  2026-09-15 23:31:55 ~ 2026-09-29 23:15:27 (14 days)
Snapshots       364 files, 0 corrupted skipped
Cleaned records 18,200 (main hot-search board)
Lessons
Design decisions hardened after running into each of these:
- The board endpoint returns four boards at once (main / rising / entertainment / pinned news). The same topic can appear on several of them with different heat semantics — this is not duplicated data, and co-occurrence on vertical boards is itself a coding variable;
- Topics without a host have no header card at all, roughly 40% of the time. That is a real phenomenon rather than a parsing defect, and it is kept as a valid coding category;
- Data cleaning is implemented in exactly one place, shared by the charts and the pivot table, so the same filter can never produce two different numbers;
- Pivot totals are aggregated independently per row and per column: only additive metrics (record counts) are summed, while distinct-count and peak metrics are taken at their own scope.
Roadmap
- Automatic topic categorisation to support coding of the three-layer agenda share
- Batch collection of post details for topic modelling and micro-layer analysis
- Monthly snapshot archiving and compression
- Cross-topic host network analysis
The system is privately deployed and currently collecting around the clock.
Changelog
- 2026.09.15
- Got Weibo's official mobile API working, parsing both the hot-search boards and the topic host field
- First snapshot written to disk; fixed-interval collection started
- 2026.09.16
- Deployed to an Alibaba Cloud ECS instance: systemd service behind a reverse proxy, starting on boot
- Shipped the web admin panel and session-expiry push notifications
- 2026.09.24
- Added the pivot table: row-by-column cross tabulation with CSV export
- Migrated to a standalone site: own domain, own certificate and config, decoupled from other projects on the same host
- 2026.09.29
- 14 days of uninterrupted collection: 364 snapshots, 18,200 cleaned records
Related Projects